01 About
I am a postdoctoral researcher with J.M.M. Montiel at the Universidad de Zaragoza, working on EndoCartoScope, an EIC Transition project building Spatial AI for medical endoscopy.
PhD in single-view depth and uncertainty for endoscopy at the Universidad de Zaragoza (2023), advised by Javier Civera and Ruben Martinez-Cantin. Visiting researcher at ASL, ETH Zurich, and previously five years in industry working on visual SLAM and augmented reality.
02 My Research
-
2025
EndoCartoScope: Spatial AI for Medical Endoscopy
abstract
We have won an EIC Transition grant from the European Innovation Council to turn our research on SLAM and depth estimation for endoscopy into a product. EndoCartoScope is a software-only spatial AI layer for standard flexible endoscopes: it builds a real-time 3D map of the explored cavity from the camera feed alone while localising the endoscope inside it, measures how much of the mucosa has been inspected, and estimates the metric size of polyps and lesions, without hardware modifications. The project is led by the Universidad de Zaragoza, with IIS Aragón as clinical validator, and takes the technology from TRL4 to TRL6 on the way to a spin-off.
-
Automated vision-based assistance tools in bronchoscopy: stenosis severity estimation
abstract
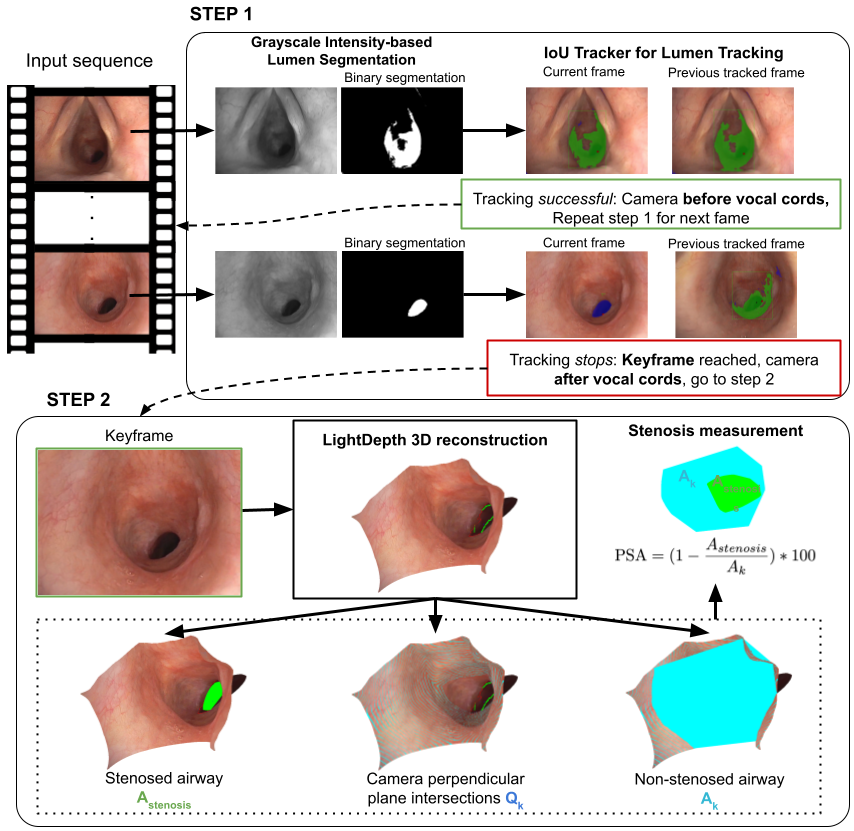
Subglottic stenosis refers to the narrowing of the subglottis, the airway between the vocal cords and the trachea. Its severity is typically evaluated by estimating the percentage of obstructed airway. No public methods or datasets are currently available for automated evaluation of this condition from bronchoscopy video. We propose a pipeline for automated subglottic stenosis severity estimation during the bronchoscopy exploration, without requiring the physician to traverse the stenosed region. Our approach exploits the physical effect of illumination decline in endoscopy to segment and track the lumen and obtain a 3D model of the airway. This 3D model is obtained from a single frame and is used to measure the airway narrowing. The results show consistency with ground-truth estimations from CT scans and expert estimations, and reliable repeatability across multiple estimations on the same patient. Additionally, we release the first public benchmark for subglottic stenosis severity assessment.
-
3D Densification for Multi-Map Monocular VSLAM in Endoscopy
abstract
Multi-map Sparse Monocular visual Simultaneous Localization and Mapping applied to monocular endoscopic sequences has proven efficient to robustly recover tracking after the frequent losses in endoscopy due to motion blur, temporal occlusion, tools interaction or water jets. The sparse multi-maps are adequate for robust camera localization, however they are very poor for environment representation. We propose a method to remove outliers and densify the maps of the state of the art for sparse endoscopy multi-map CudaSIFT-SLAM. The NN LightDepth for up-to-scale depth dense predictions are aligned with the sparse CudaSIFT submaps by means of the robust to spurious LMedS. Our system mitigates the inherent scale ambiguity in monocular depth estimation while filtering outliers, leading to reliable densified 3D maps. We provide experimental evidence of accurate densified maps 4.15 mm RMS accuracy at affordable computing time in the C3VD phantom colon dataset. We report qualitative results on the real colonoscopy from the Endomapper dataset.
-
2024
Uncertainty and Self-Supervision in Single-View Depth
abstract
Single-view depth estimation is an ill-posed problem because there are multiple depth solutions that explain 3D geometry from a single view. While deep neural networks have been shown to be effective at capturing depth from a single view, the majority of current methodologies are deterministic in nature. We have addressed this problem by quantifying the uncertainty of supervised single-view depth for Bayesian deep neural networks. There are scenarios, especially in medicine in the case of endoscopic images, where annotated data is not available. We introduce an uncertainty-aware teacher-student architecture that is trained in a self-supervised manner, taking into account the teacher uncertainty. Finally, we advocate a fully self-supervised approach that only requires RGB images and the geometric and photometric calibration of the endoscope, and propose the use of illumination as a strong single-view self-supervisory signal for deep neural networks.
-
2023
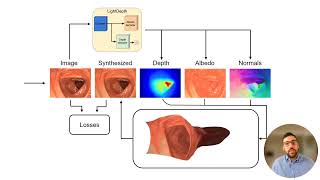
LightDepth: Single-View Depth Self-Supervision from Illumination Decline
abstract
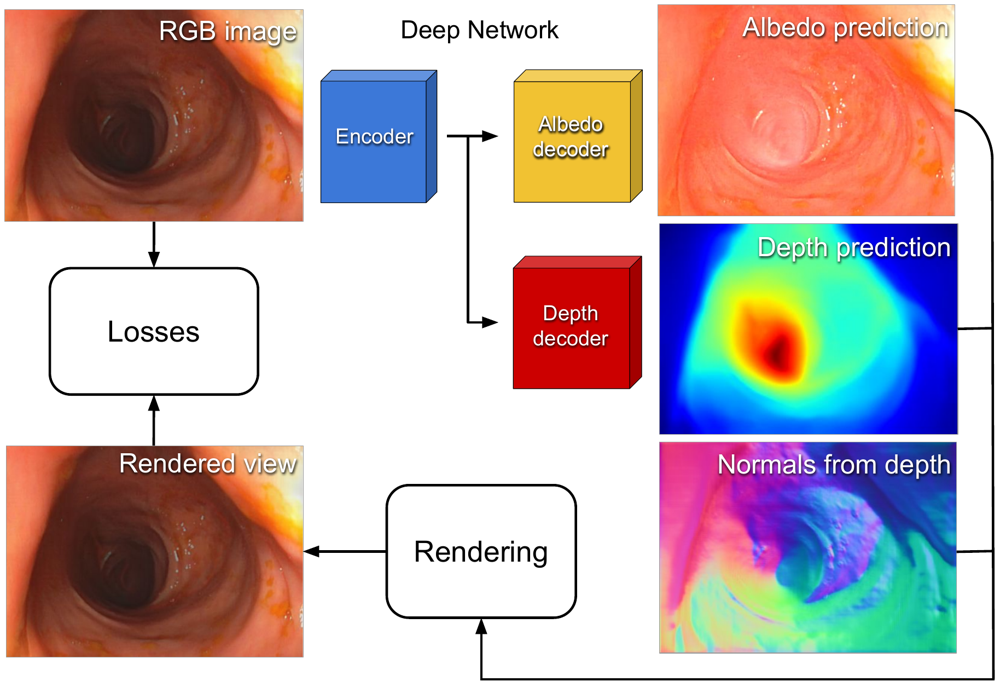
Single-view depth estimation can be remarkably effective if there is enough ground-truth depth data for supervised training. However, there are scenarios, especially in medicine in the case of endoscopies, where such data cannot be obtained. In such cases, multi-view self-supervision and synthetic-to-real transfer serve as alternative approaches, however, with a considerable performance reduction in comparison to supervised case. Instead, we propose a single-view self-supervised method that achieves a performance similar to the supervised case. In some medical devices, such as endoscopes, the camera and light sources are co-located at a small distance from the target surfaces. Thus, we can exploit that, for any given albedo and surface orientation, pixel brightness is inversely proportional to the square of the distance to the surface, providing a strong single-view self-supervisory signal. In our experiments, our self-supervised models deliver accuracies comparable to those of fully supervised ones, while being applicable without depth ground-truth data.
-
3D VSG: Long-term Semantic Scene Change Prediction through 3D Variable Scene Graphs
abstract
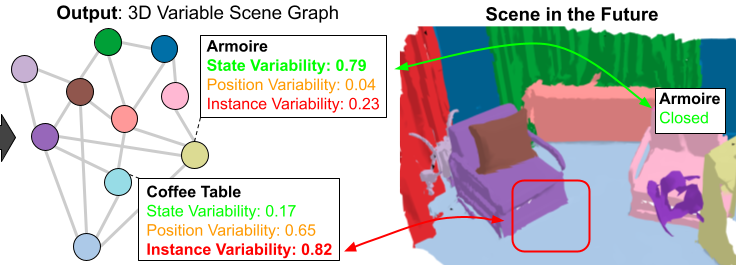
Numerous applications require robots to operate in environments shared with other agents, such as humans or other robots. However, such shared scenes are typically subject to different kinds of long-term semantic scene changes. The ability to model and predict such changes is thus crucial for robot autonomy. In this work, we formalize the task of semantic scene variability estimation and identify three main varieties of semantic scene change: changes in the position of an object, its semantic state, or the composition of a scene as a whole. To represent this variability, we propose the Variable Scene Graph (VSG), which augments existing 3D Scene Graph (SG) representations with the variability attribute, representing the likelihood of discrete long-term change events. We present a novel method, DeltaVSG, to estimate the variability of VSGs in a supervised fashion.
-
2022
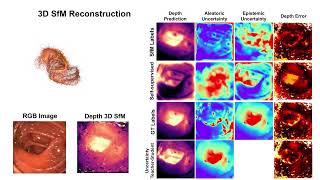
On the Uncertain Single-View Depths in Colonoscopies
abstract
Estimating depth information from endoscopic images is a prerequisite for a wide set of AI-assisted technologies, such as accurate localization and measurement of tumors, or identification of non-inspected areas. As the domain specificity of colonoscopies -- deformable low-texture environments with fluids, poor lighting conditions and abrupt sensor motions -- pose challenges to multi-view 3D reconstructions, single-view depth learning stands out as a promising line of research. In this paper, we explore for the first time Bayesian deep networks for single-view depth estimation in colonoscopies. Our specific contribution is two-fold: 1) an exhaustive analysis of scalable Bayesian networks for depth learning in different datasets, highlighting challenges and conclusions regarding synthetic-to-real domain changes and supervised vs. self-supervised methods; and 2) a novel teacher-student approach to deep depth learning that takes into account the teacher uncertainty.
-
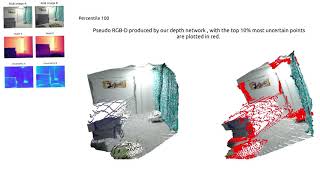
Bayesian Deep Networks for Supervised Single-View Depth Learning
abstract
Uncertainty quantification is a key aspect in robotic perception, as overconfident or point estimators can lead to collisions and damages to the environment and the robot. In this paper, we evaluate scalable approaches to uncertainty quantification in single-view supervised depth learning, specifically MC dropout and deep ensembles.
-
2018
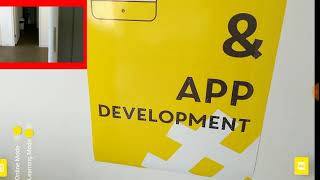
Localization Service Using Sparse Visual Information Based on Recent Augmented Reality Platforms
abstract
We propose a localization service based on sparse visual information using ARCore, a state-of-the-art augmented reality platform for mobile devices. Our service is constituted by two components - front-end and back-end. On the front-end, using the point cloud generated by ARCore as feature points, a corresponding binary keypoint descriptor algorithm like ORB or FREAK is computed to describe the place. On the back-end, this binary descriptor is searched in a map using the bags of binary words technique, responding with the position of the recognized place.
-
2017
Obstacle Collision Avoidance System for visually impaired based on Tango
abstract
In order to move freely around the space, a user could use this system as a virtual white cane. The Obstacle Collision Avoidance System intends to assist visually impaired people during the obstacle avoidance process using the depth perception of a Tango enable device.
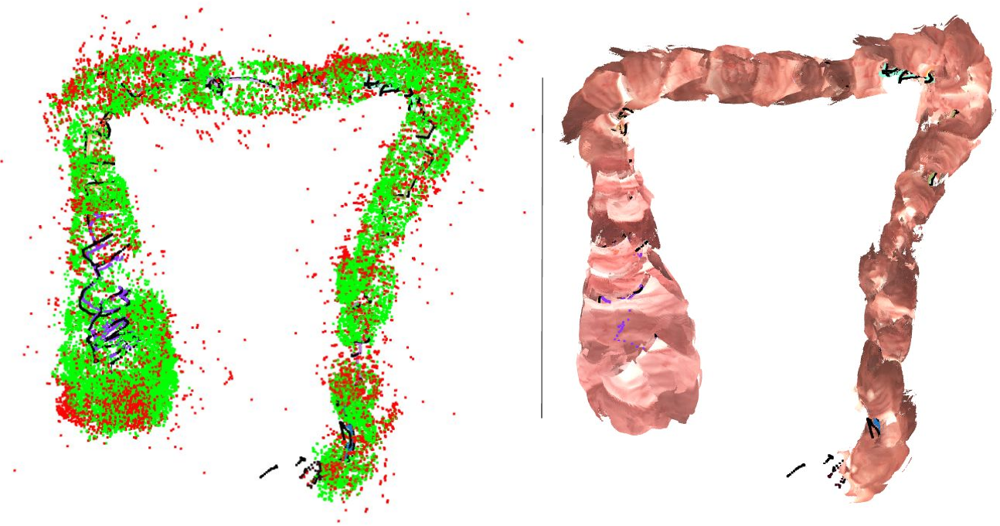
03 Projects and Grants
-
2025 – 2028
EndoCartoScope: Transforming any Endoscope into a Smart Device for Intraoperative 3D Localization, Navigation and Mapping
Team member · Horizon EIC 2024 Transition Open
-
Mar 2021 – Nov 2024
-
2020 – 2023
FPI predoctoral grant PRE2019-090875
Recipient · Spanish Ministry of Science and Innovation, Agencia Estatal de Investigación
04 Experience
-
Jan 2024 – present
Postdoctoral Researcher
Robotics, Perception and Real Time Group (RoPeRT), Universidad de Zaragoza · Zaragoza, Spain
-
Jan 2020 – Dec 2023
PhD Researcher
Robotics, Perception and Real Time Group (RoPeRT), Universidad de Zaragoza · Zaragoza, Spain
-
Feb 2022 – Aug 2022
Visiting Researcher
Autonomous Systems Lab, ETH Zürich · Zürich, Switzerland
-
Aug 2014 – Dec 2019
Software Developer
Cologne Intelligence GmbH · Cologne, Germany
-
Sep 2013 – Aug 2014
Student Software Developer
Grandcentrix GmbH · Cologne, Germany
05 Talks and more